- SpaceXAI released Grok 4.7 on September 21 at $2 per million input tokens and $6 per million output, unchanged from Grok 4.6, on the Grok API, Cursor, and Grok Build.
- On the independent Terminal-Bench 4.0 agentic coding test, Grok 4.7 scored 26 percent, against 60 percent for GPT-6 Astra and 55 percent for Claude Fable 5.1.
- The model keeps a 500,000-token context window and adds an xhigh reasoning level aimed at coding tasks that run for hours.
SpaceXAI released Grok 4.7 on Sunday, its most capable coding model to date by the company's own account, at token prices that sit closer to China's open models than to Western frontier systems. The release reached the Grok API, Cursor, and Grok Build the same day. What the low pricing buys, on independent testing, is a model that reasons for longer and checks its own work more carefully, and still finishes well behind the frontier on exactly the coding work SpaceXAI is positioning it for.
Grok 4.7 holds Grok 4.6 pricing and a 500,000-token context window
SpaceXAI describes Grok 4.7 as a larger base model trained with a longer reinforcement learning run, weighted toward problems that take many hours, and designed to better verify its own output. The pricing matches Grok 4.6 to the cent: $2 per million input tokens and $6 per million output below 200,000 tokens, then $4 and $12 above that threshold. The context window stays at 500,000 tokens, and the model exposes four reasoning levels from low through the new xhigh setting.
On SpaceXAI's own scoring, every coding number moves up. CursorBench 4.0 rises to 46.3 percent from 40.4, DeepSWE v1.1 to 71.0 from 65.2, and Terminal-Bench 4.0 to 38.0 from 20.3, the largest single gain in the release.
| $2 / $6 | Price per million input / output tokens below 200k, unchanged from Grok 4.6 (doubles above 200k) |
| 500,000 | Context window in tokens, unchanged from Grok 4.6 |
| 46 | Artificial Analysis Intelligence Index score, against 53 for GPT-6 and Claude Fable 5.1 |
| 26% | Independent Terminal-Bench 4.0 agentic coding score, against SpaceXAI's self-reported 38% |
Its most capable model yet for coding and knowledge work.SpaceXAI, Grok 4.7 release
Independent coding benchmarks put Grok 4.7 far behind GPT-6 and Claude
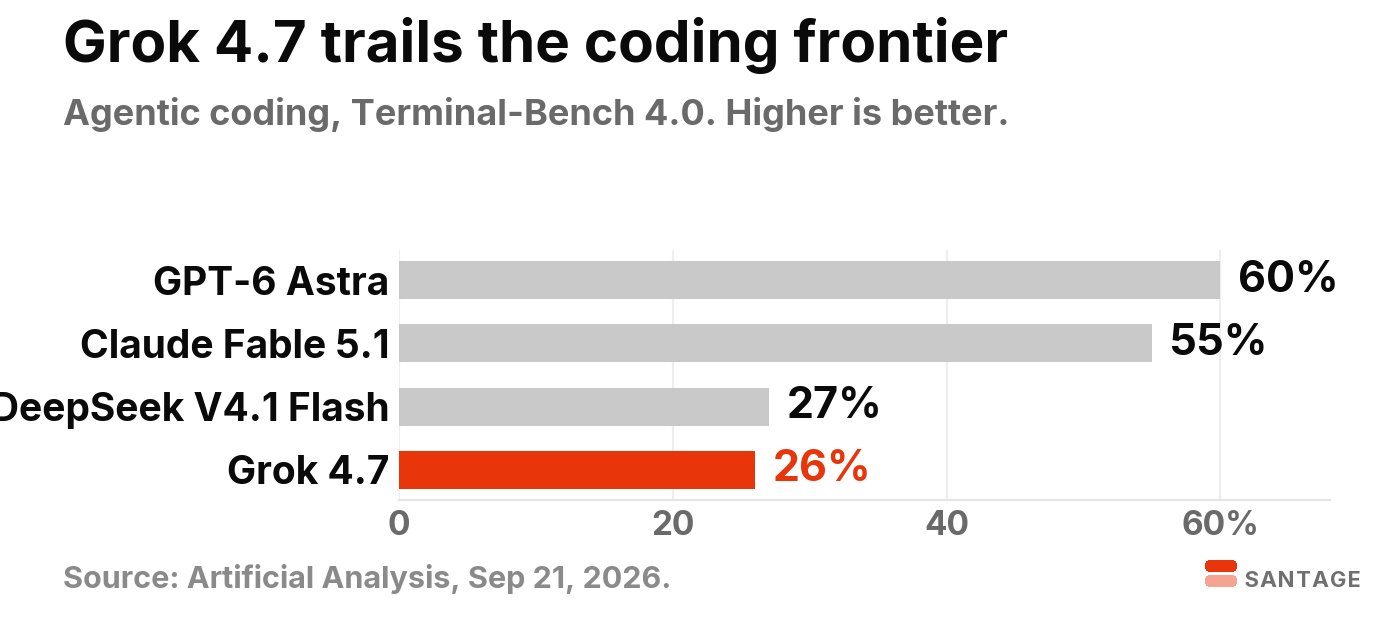
On the Artificial Analysis Intelligence Index v4.3.2, which blends ten benchmarks, Grok 4.7 scored 46, against 53 for both GPT-6 and Claude Fable 5.1. The gap widens on agentic coding, the capability SpaceXAI foregrounds. Independent Terminal-Bench 4.0 scoring placed Grok 4.7 at 26 percent, behind GPT-6 Astra at 60 and Claude Fable 5.1 at 55, and a shade behind DeepSeek V4.1 Flash at 27. SpaceXAI's own Terminal-Bench figure of 38 percent, measured at the xhigh setting, sits well above the independent result, a spread worth tracking as third-party evaluations settle.
The pricing is where Grok 4.7 makes its case. At $2 per million input tokens, it undercuts GPT-6 and Claude by a wide margin and lands in the range Chinese labs have used to win developer volume. For a coding agent that runs thousands of calls a day, that difference compounds fast.
At token rates that track China's open models rather than the frontier, Grok 4.7 is built to be run cheaply at scale rather than to top a leaderboard. That is a coherent bet for SpaceXAI only if buyers decide cost per task matters more than the last twenty points of coding accuracy, and the frontier labs are betting the opposite.
Santage is committed to independent, transparent journalism. This article is produced in accordance with Santage's Editorial Standards and aims to provide accurate and timely information. Readers are encouraged to verify information independently.